

Time series forecasting discussions quickly drift toward increasingly elaborate models: ARIMA, LSTMs, Transformers, gradient boosting, state-space models, and whatever new architecture is currently being sold as “adaptive intelligence” by people with suspiciously clean equity curves.
But sometimes, a simpler question is more useful:
Can we forecast a time series by asking: “When the past looked like this before, what happened next?”
That is the intuition behind k-nearest neighbors regression, or KNN regression. In this article, we will build a simple autoregressive KNN forecaster, then extend it into an Aggregate KNN Time Series Forecaster that combines multiple neighborhood sizes.
The idea is straightforward:
Instead of choosing one arbitrary number of neighbors, we use several:
[2, 3, 5, 10, 15, 20, 30, 40, 50, 100]Each KNN model produces a forecast. The aggregate model then takes the median forecast across them. For directional analysis, each model can also “vote” on whether the next value is expected to rise or fall.
Then we compare the aggregate KNN model against three simple benchmarks:
KNN with 5 neighbors
KNN with 10 neighbors
KNN with 20 neighbors
The objective is not to pretend that KNN has discovered the hidden machinery of the economy. It has not. The objective is to test whether aggregating across multiple neighborhood assumptions gives a more stable forecast than relying on a single value of k.
For the dataset, we will use the U.S. unemployment rate from FRED. The series is monthly, seasonally adjusted, expressed in percent, and sourced from the U.S. Bureau of Labor Statistics. FRED also makes time series available as downloadable CSV files, which is convenient because nobody should have to construct a data pipeline just to test a basic forecasting idea.
1. A Basic Introduction to Time Series
A time series is simply a sequence of observations ordered through time.
Examples include:
Monthly unemployment rate
Daily closing price of the S&P 500
Quarterly GDP growth
Weekly initial jobless claims
Hourly electricity demand
The important point is that time series data is ordered. The order matters.
In a normal regression problem, the rows are often assumed to be independent. In time series forecasting, yesterday, last month, and last quarter often contain information about today. That is why we usually transform a time series into an autoregressive learning problem.
Suppose we have a series:
y1, y2, y3, y4, ..., ytA simple one-step-ahead autoregressive model tries to predict the next value using lagged values:
yt = f(yt-1, yt-2, yt-3, ..., yt-n)In plain English:
Given the last
nobservations, predict the next one.
For example, if we use 12 monthly lags, then each training example contains the previous 12 months of unemployment data, and the target is the next month’s unemployment rate.
This turns a time series into a supervised learning dataset.
2. What KNN Regression Does
K-nearest neighbors regression is one of the simplest machine learning methods.
It does not estimate a complex parametric equation. It does not learn coefficients like linear regression. It does not build trees. It simply stores historical examples and, when asked to predict a new point, finds the most similar historical points.
In scikit-learn, KNeighborsRegressor predicts a continuous value by looking at the target values associated with the nearest neighbors in the training set. The number of neighbors is controlled by the n_neighbors parameter.
For a time series, the logic becomes:
Find historical periods where the previous observations looked similar to the current previous observations. Then average what happened next in those historical periods.
If k = 5, the model finds the 5 most similar historical lag patterns and averages their next values.
If k = 20, it uses a broader neighborhood.
The value of k matters. A small k can be reactive but noisy. A large k can be stable but slow and overly smooth. Scikit-learn’s own documentation notes the general trade-off that larger neighborhood sizes can suppress noise but make boundaries less distinct.
That is the entire motivation for aggregation.
3. Why Aggregate Across Many K Values?
Choosing one value of k is often arbitrary.
A 5-neighbor KNN may work better during sharp cyclical shifts. A 50-neighbor KNN may work better in slow-moving regimes. A 100-neighbor KNN may behave like a very smooth historical average.
The problem is that we do not know in advance which neighborhood size will be best.
So instead of selecting one, we build a committee.
The Aggregate KNN model uses:
neighbors = [2, 3, 5, 10, 15, 20, 30, 40, 50, 100]Each model generates a forecast:
KNN(2) forecast
KNN(3) forecast
KNN(5) forecast
...
KNN(100) forecast
The final forecast is the median of all forecasts:
Aggregate Forecast = median(all KNN forecasts)The median is useful because it is less sensitive to extreme individual forecasts. If one very small-neighborhood model becomes unstable, the median dampens its influence.
For direction, we can also ask each model to vote:
Does this model predict the next value will rise or fall?The final directional call is based on the majority vote.
This gives us two outputs:
1. Median forecast value
2. Majority directional vote
Simple. Transparent. Annoyingly sensible.
4. Fetching the Economic Time Series
We will use the U.S. unemployment rate, series code UNRATE, from FRED.
At the time of writing, FRED lists UNRATE as a monthly, seasonally adjusted series measured in percent, sourced from the U.S. Bureau of Labor Statistics. The latest listed observation on the FRED page is June 2026 at 4.2%, updated on July 2, 2026.
Here is the Python code to download it directly:
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt

from sklearn.neighbors import KNeighborsRegressor
from sklearn.preprocessing import StandardScaler
from sklearn.pipeline import Pipeline
from sklearn.metrics import mean_absolute_error, mean_squared_error


SERIES = "UNRATE"

url = f"https://fred.stlouisfed.org/graph/fredgraph.csv?id={SERIES}"

df = pd.read_csv(url)

df.columns = ["date", "value"]
df["date"] = pd.to_datetime(df["date"])
df["value"] = pd.to_numeric(df["value"], errors="coerce")

df = df.dropna().set_index("date")

df = df.diff()
df = df.dropna()

print(df.tail())
This gives us a clean monthly time series.
🚨 Get your Quant Atlas Free trial (no credit card required) 🚨
Sign up takes ~9 seconds before you have unconditional 10-day access to 100+ market forecasts.
5. Turning the Series Into a Supervised Learning Problem
We now transform the time series into lagged features.
For each date, the model sees the previous 12 observations and tries to predict the current observation.
def make_lagged_frame(series, n_lags=12):
    data = pd.DataFrame({"y": series})

    for lag in range(1, n_lags + 1):
        data[f"lag_{lag}"] = series.shift(lag)

    data = data.dropna()
    return data


n_lags = 12

data = make_lagged_frame(df["value"], n_lags=n_lags)

X = data.drop(columns=["y"])
y = data["y"]
Each row now looks like this:
Target: current unemployment rate

Features:
lag_1  = unemployment rate one month ago
lag_2  = unemployment rate two months ago
...
lag_12 = unemployment rate twelve months ago
This is an autoregressive machine learning setup.
6. Walk-Forward Forecasting
For time series, random train-test splits are usually a terrible idea dressed as convenience.
We need to respect time.
So we use a walk-forward backtest:
Train on the first part of the data.
Predict the next observation.
Expand the training window.
Predict the next observation.
Repeat until the end.
This mimics how the model would have behaved in real time.
def make_knn_model(n_neighbors):
    return Pipeline([
        ("scaler", StandardScaler()),
        ("knn", KNeighborsRegressor(
            n_neighbors=n_neighbors,
            weights="uniform"
        ))
    ])
The scaler is important because KNN uses distances. If features are on different scales, distance calculations can become distorted. Here, all features are lagged values from the same series, but scaling is still a good habit.
Now we create the walk-forward engine.
def walk_forward_knn(X, y, benchmark_neighbors, aggregate_neighbors, min_train_size=120):
    rows = []

    for i in range(min_train_size, len(X)):
        X_train = X.iloc[:i]
        y_train = y.iloc[:i]

        X_test = X.iloc[[i]]
        actual = y.iloc[i]
        date = y.index[i]

        last_known_value = X_test["lag_1"].iloc[0]

        row = {
            "date": date,
            "actual": actual,
            "last_known": last_known_value
        }

        # Benchmark KNN models
        for k in benchmark_neighbors:
            model = make_knn_model(k)
            model.fit(X_train, y_train)

            pred = model.predict(X_test)[0]
            row[f"knn_{k}"] = pred
            row[f"knn_{k}_direction"] = np.sign(pred - last_known_value)

        # Aggregate KNN model
        aggregate_predictions = []

        for k in aggregate_neighbors:
            adjusted_k = min(k, len(X_train))

            model = make_knn_model(adjusted_k)
            model.fit(X_train, y_train)

            pred = model.predict(X_test)[0]
            aggregate_predictions.append(pred)

        aggregate_predictions = np.array(aggregate_predictions)

        row["aggregate_knn"] = np.median(aggregate_predictions)

        votes = np.sign(aggregate_predictions - last_known_value)
        vote_sum = np.sum(votes)

        if vote_sum > 0:
            row["aggregate_direction"] = 1
        elif vote_sum < 0:
            row["aggregate_direction"] = -1
        else:
            row["aggregate_direction"] = np.sign(row["aggregate_knn"] - last_known_value)

        rows.append(row)

    results = pd.DataFrame(rows).set_index("date")
    return results
Now define the models:
benchmark_neighbors = [5, 10, 20]

aggregate_neighbors = [2, 3, 5, 10, 15, 20, 30, 40, 50, 100]

results = walk_forward_knn(
    X=X,
    y=y,
    benchmark_neighbors=benchmark_neighbors,
    aggregate_neighbors=aggregate_neighbors,
    min_train_size=120
)

print(results.tail())
7. Evaluation Metrics
We will use three simple evaluation metrics:
MAE: mean absolute error
RMSE: root mean squared error
Directional Accuracy: percentage of times the model correctly predicted rise/fall
MAE is intuitive: average absolute forecast error.
RMSE penalizes large errors more strongly.
Directional accuracy asks whether the model got the direction right relative to the previous known value.
def evaluate_forecasts(results, forecast_columns):
    evaluation = []

    actual_direction = np.sign(results["actual"] - results["last_known"])

    for col in forecast_columns:
        forecast = results[col]

        mae = mean_absolute_error(results["actual"], forecast)
        rmse = np.sqrt(mean_squared_error(results["actual"], forecast))

        forecast_direction = np.sign(forecast - results["last_known"])

        valid = actual_direction != 0

        directional_accuracy = (
            forecast_direction[valid] == actual_direction[valid]
        ).mean()

        evaluation.append({
            "model": col,
            "MAE": mae,
            "RMSE": rmse,
            "Directional Accuracy": directional_accuracy
        })

    evaluation = pd.DataFrame(evaluation)
    evaluation = evaluation.sort_values("RMSE")

    return evaluation


forecast_columns = [
    "knn_5",
    "knn_10",
    "knn_20",
    "aggregate_knn"
]

evaluation = evaluate_forecasts(results, forecast_columns)

print(evaluation)
The table will show whether the aggregate KNN produces a measurable lift over the single-neighbor-count benchmarks.
For example, the structure will look like this:
           model       MAE      RMSE  Directional Accuracy
3  aggregate_knn  0.148362  0.423939              0.798354
2         knn_20  0.150637  0.426701              0.803841
1         knn_10  0.153639  0.430065              0.791495
0          knn_5  0.157550  0.435714              0.775034
The exact values will depend on the latest available FRED data when the script is run.
8. Visualizing the Forecasts
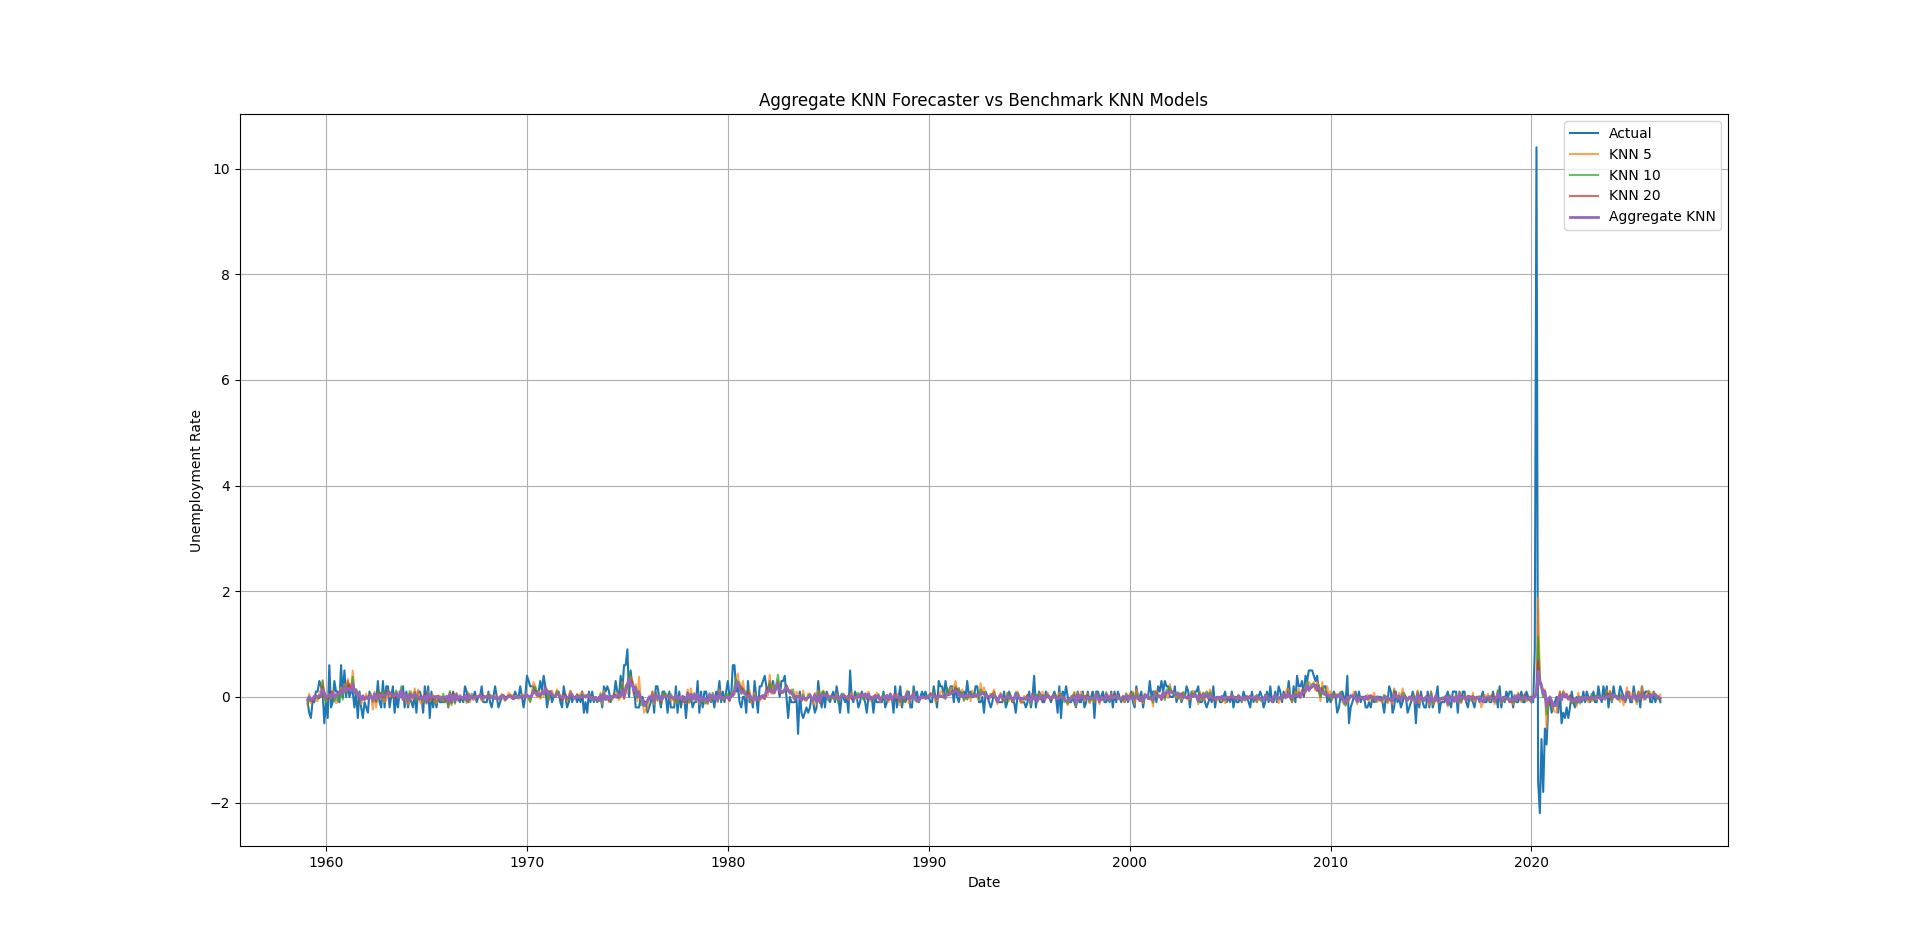
A table is useful, but a plot helps show how smooth or reactive each model is.
plt.figure(figsize=(12, 6))

plt.plot(results.index, results["actual"], label="Actual")
plt.plot(results.index, results["knn_5"], label="KNN 5", alpha=0.7)
plt.plot(results.index, results["knn_10"], label="KNN 10", alpha=0.7)
plt.plot(results.index, results["knn_20"], label="KNN 20", alpha=0.7)
plt.plot(results.index, results["aggregate_knn"], label="Aggregate KNN", linewidth=2)

plt.title("Aggregate KNN Forecaster vs Benchmark KNN Models")
plt.xlabel("Date")
plt.ylabel("Unemployment Rate")
plt.legend()
plt.grid(True)
plt.show()
The benchmark models should behave differently:
KNN 5: more reactive, potentially noisier
KNN 10: moderate smoothing
KNN 20: smoother, slower response
Aggregate KNN: median blend across many assumptions
The aggregate model is not guaranteed to win. That is the point of testing. A model that always wins in the author’s backtest usually belongs in the same intellectual category as miracle diets and trading screenshots with the broker name cropped out.
9. What Would Count as a Real Lift?
The aggregate KNN adds value if it improves one or more of the following:
Lower MAE
Lower RMSE
Higher directional accuracy
More stable performance across different samples
Less sensitivity to one arbitrary value of k
The last point is especially important.
Even if the aggregate model does not always have the lowest error, it may still be useful if it reduces dependence on a single hyperparameter. In forecasting, robustness often matters more than theoretical elegance.
A single KNN model asks:
Which value of k is best?
The aggregate KNN asks:
Can we reduce the risk of choosing the wrong k?
That is a healthier research question.
Final Thoughts
The Aggregate KNN Time Series Forecaster is a simple model built around a practical idea:
Instead of relying on one neighborhood size, combine many.
It uses historical analogues, autoregressive lag patterns, and a median voting structure to produce a forecast that is less dependent on a single arbitrary k.
This does not make it magic. It does not make it macro-aware. It does not understand central banks, recessions, structural breaks, labor force participation, or the deep human comedy of economists revising last month’s certainty.
But it does give us a clean, testable framework:
Build several KNN forecasts.
Aggregate them.
Compare them against fixed-k benchmarks.
Measure whether the aggregation improves forecast quality.
That is the useful part.
In forecasting research, the goal is rarely to find the perfect model. The goal is to build something transparent, testable, and hard to fool.
The Aggregate KNN is a good candidate for that kind of experiment.